Explanation
On this page
A turn
Everything Nawa does happens inside a turn: the stretch between your message and the answer that ends it. A turn is one visible thing in the transcript, however long it runs and however many tools and agents it uses; there is no separate "job" the work escapes into. This page explains what happens inside one.
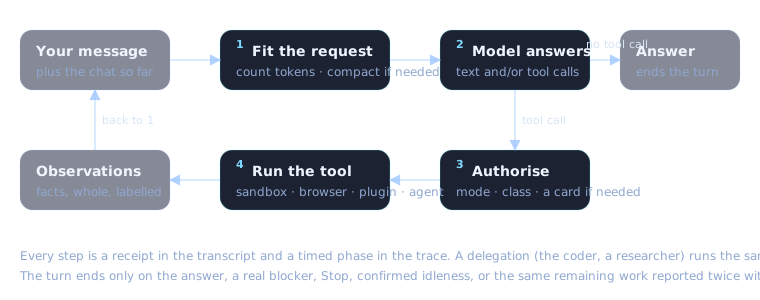
Before the first request
The engine reads the chat's history and the settings the renderer sent, resolves the active setup (the main model, and the coding model when it differs) and the decision model if one is switched on. The main model also screens external content, with its reasoning turned off. It loads the instruction files that apply — the profile's AGENTS.md, the project's, and any nested one already selected — and hands them over complete. It builds the tool list for this turn: Nawa's own tools, the workspace tools for the chat's permission mode, and the catalogue of plugins the model may load.
Then it fits the request: it materialises the exact request the provider will receive, counts its tokens, and compares the count with the model's window and the reserve it keeps for the answer. If the history is too long it compacts it — summarising the older part into a checkpoint while keeping the recent rounds and every unresolved observation verbatim — and counts again before sending. The count is token-based, never a character estimate, and where a provider offers an exact counting endpoint Nawa uses it.
The loop
- The model answers with text, tool calls, or both. Text streams to the transcript as it arrives.
- Each tool call is authorised against the turn's permission mode and the tool's security class (read, compute, workspace write, process, network, dispatch, external mutation). A call the mode does not allow pauses the turn with a permission card; your choice on the card is recorded in the trace with the time you took.
- The tool runs, and its result comes back as observations: a command's exit code, stdout and stderr; a page's elements; a file's content and version. A result too large for the model is stored whole as evidence and returned as a page the model can read further. External content — a web page, an email — is screened by the main model, in a separate request with its reasoning turned off, before the model sees it, and carries its provenance with it.
- Every result goes back to the model, and the request is fitted again. The loop continues until the model answers without a tool call.
Some tool calls are delegations: run_agent passes your original message to an agent with a context of its own — the coder, the web researcher — which runs the same loop with its own tools and reports back. Main chooses the agent. Each agent receives the same request, including when one agent calls another, and decides how to do the part that fits its role. A coder session that reaches its model's limit continues in a fresh session from a checkpoint of its own work, in the same turn and the same workspace; it is not moved to the background. Any other agent that reaches its model's limit returns what it has written as an unfinished report, with the limit it stopped at; one whose model fails partway returns what it has written beside the failure, with the names of any tool calls that never ran. However an agent ends, its result lists the steps it ran and where their results are kept, and the web researcher's also hands over the sources it selected.
Saved external evidence retains its origin on file reads. Native command output and local browser observations also inherit recorded origins when they reproduce matching text from that evidence. This copy detection is best effort: it cannot identify arbitrary transformations or new content fetched outside Nawa's source tools, and reports incomplete scans when a saved source cannot be checked.
Ending
A turn ends when the model has answered and, for a turn that did work, when it has called the turn's terminal tool with its result — the harness demands that tool when an answer arrives without it, so a build cannot be reported as done by prose alone. It ends earlier on a genuine blocker, on your Stop generating, when the watchdog finds the work idle, or on genuine non-convergence: the exact same remaining work reported twice with the same authoritative progress. Elapsed time and turn counts are never the reason.
References in progress narration, final answers and automation results use the same publication checks. Local files must exist and be readable, citation identities must be available, and an application preview must have been published through the verified artifact path. An unavailable reference returns its exact failure to the model in the same turn; Nawa does not silently replace a broken link or remove an invalid preview. These checks establish resource availability, not whether every sentence about it is true. Interpreting results and writing accurate narration remain the model's responsibility.
A turn you stop ends once, as stopped, never as a failure, and keeps the answer written so far; the next turn receives that answer and the fact that you stopped the turn. When you close Nawa during a turn, it waits briefly for the interruption record and unfinished answer to be saved. Reopening restores that answer in a closed Unverified draft card, and the turn ends with a plain message saying it was interrupted. Your next message receives the saved answer and interruption record; Nawa does not resume automatically. A forced process termination can preserve only what reached storage before it ended. A turn that fails also keeps the answer written so far with its failure. A stopped or failed answer stays in the closed draft card until you open it because it has not passed the checks an answer passes. The card contains the plain text the model wrote. A failure records whether the model produced private reasoning, never the reasoning itself.
What is kept
- The transcript: your message, the narration, every tool receipt, the answer — the memory of the chat.
- The trace: one record per phase (request preparation, model request, tool execution, screening, decisions, compaction) with timings and token counts, keyed by the trace id shown with any error, in
data\runtime\trace-index.jsonl. - The workspace: the chat's files, with checkpoint commits as the undo mechanism: one for each coder dispatch, and one for the lead's own changes in a turn. A turn's checkpoint is committed after the turn has ended, and so is that of an agent a stop interrupted, so a stop shows when it happens even while those commits wait for other Nawa work; a message you send meanwhile starts once they are committed.
- Memory, when it is on: durable facts about you, kept in one store the model maintains with your approval.
Why it is shaped this way
- One visible work model, because a build that disappears into a background path is a build the user cannot see or stop.
- Fitting before every request, because a request the provider truncates silently is worse than one that is compacted openly; the compaction is itself an event in the transcript.
- Observations rather than verdicts in tool results, because an exit code is data (
rgexits 1 for "no matches") and the model, not the harness, decides what it means. - Convergence by authoritative progress rather than by clocks, because productive work has no stopwatch and stalled work has no excuse.
The notes docs/compaction-unification-2026-09-14.md, docs/context-accounting-2026-09-14.md and docs/continuation-and-controls-2026-09-15.md in the source tree record the measurements behind these rules.