Reference
On this page
Budgets
Budgets put limits on how much work Nawa does at once and how large each model request may be. The shipped values suit most setups; change them when a provider or a machine needs it. For what the composer's token numbers mean, see Tokens and budgets.
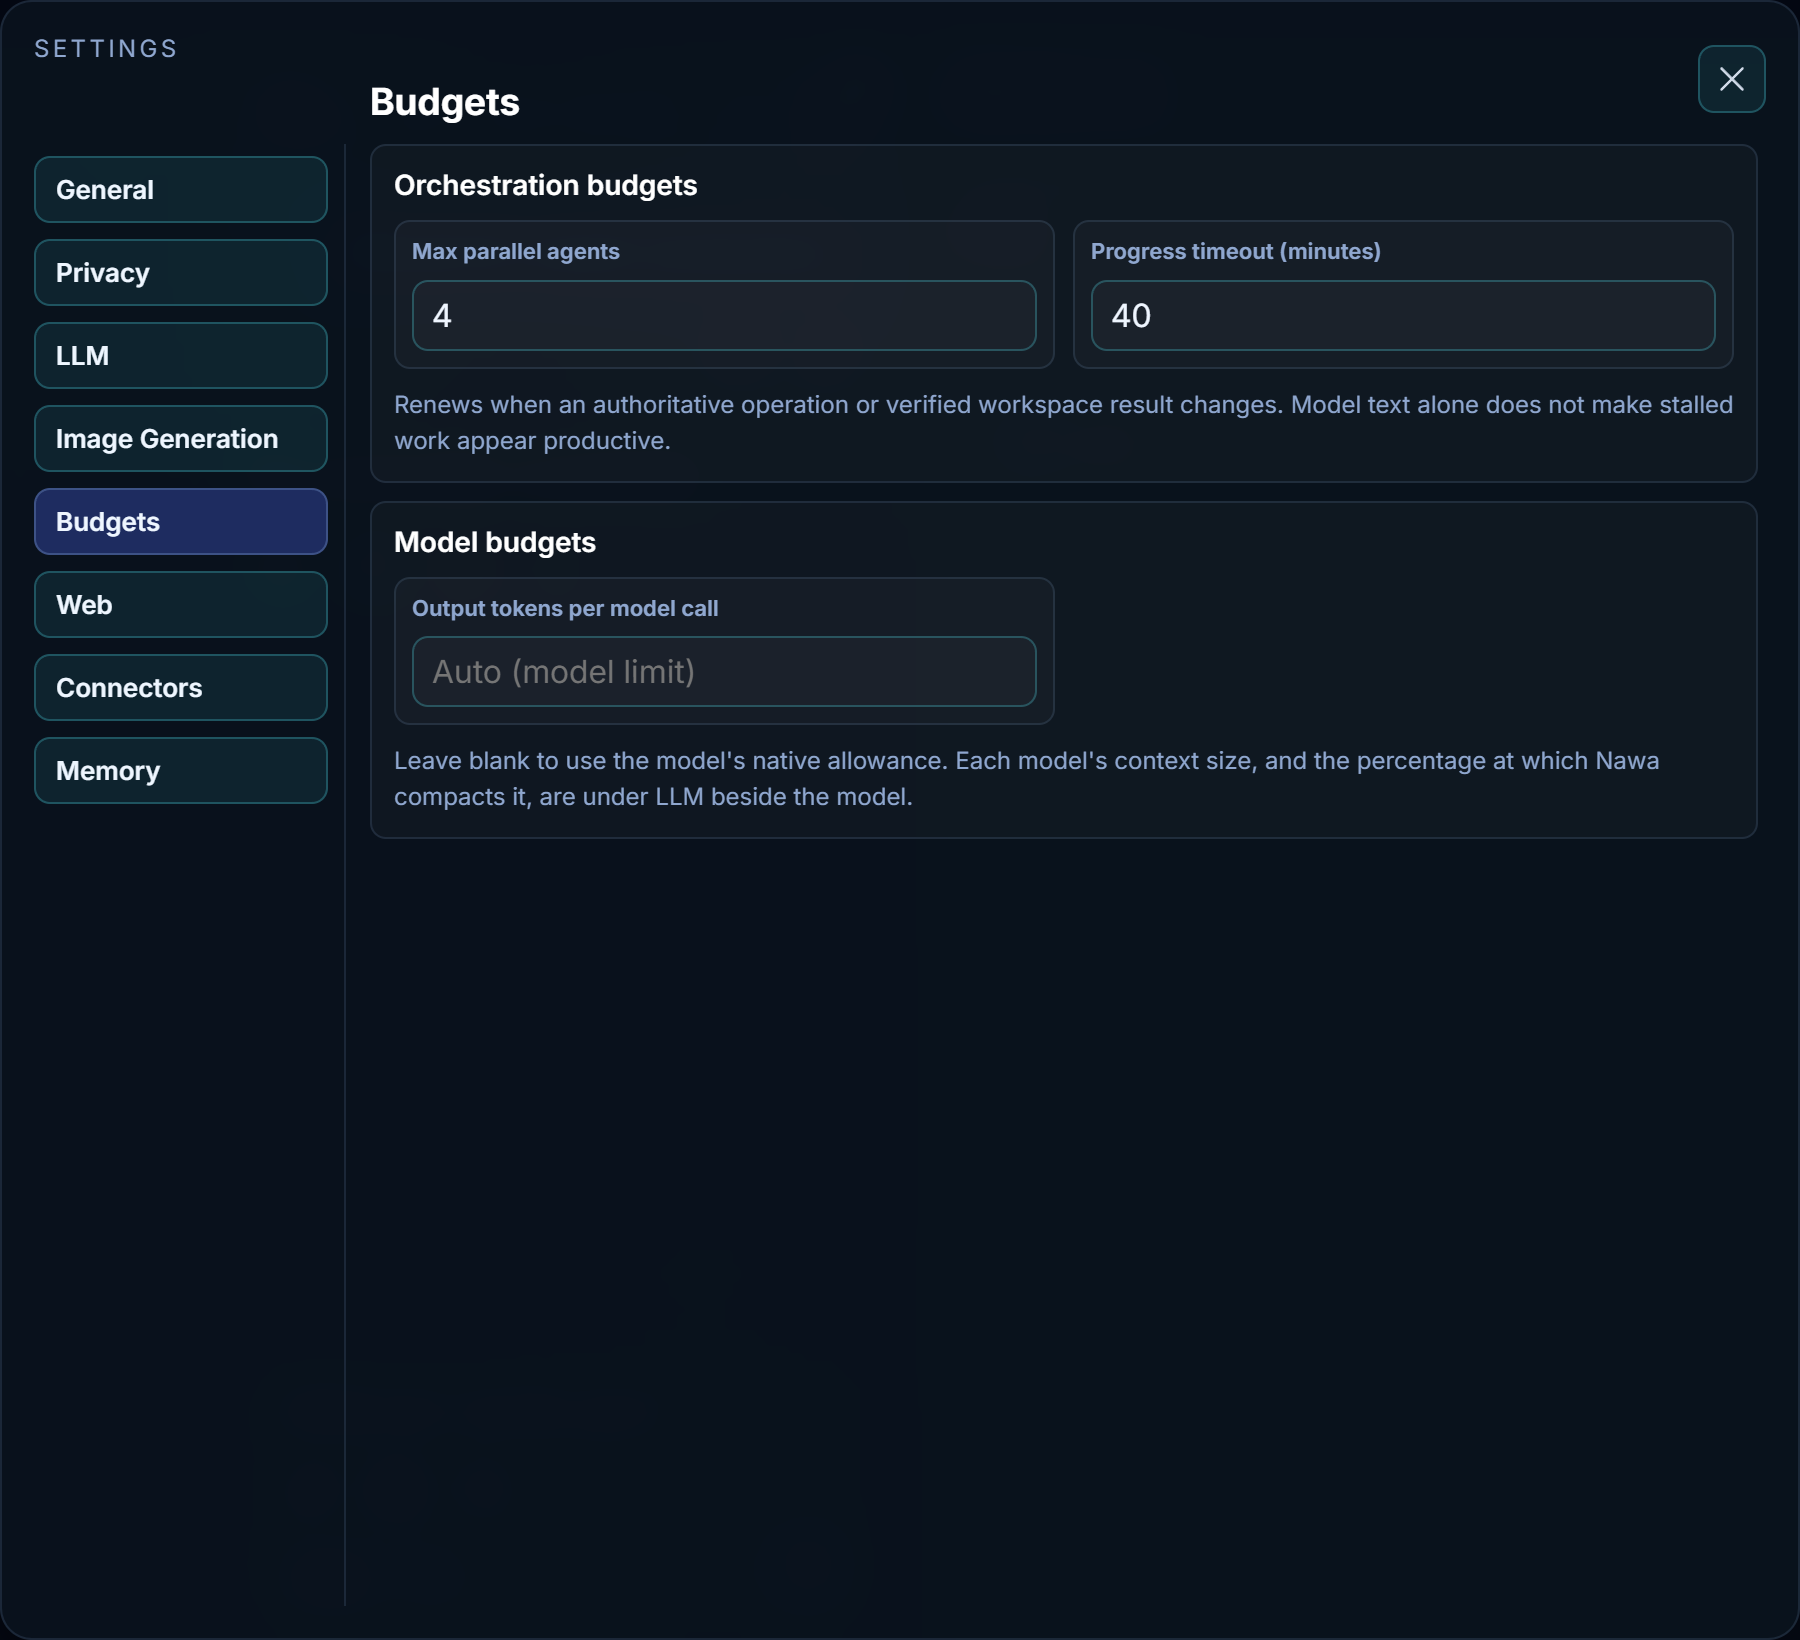
Orchestration budgets
- Max parallel agents
- How many agents, such as researchers and the coder, may run at the same time within a task. From 1 to 8; the shipped value is 4. It applies to cloud providers; agents that share a model server on your own machine or network run at most two at a time, whatever this value says. Lower it if a provider slows down or rejects requests under parallel load.
- Progress timeout (minutes)
- How long work may go without progress before Nawa stops it as stalled. From 1 to 120; the shipped value is 40. The clock restarts whenever a real operation finishes or a verified workspace result changes, so long but productive work is never cut off. Model text alone does not restart it.
Model budgets
- Output tokens per model call
- The most a single model reply may contain. Blank, shown as Auto (model limit), uses the model's own allowance; any value must be at least 256. A low limit can cut useful replies short.
A model's context size comes from the model itself, and nobody sets it. The LLM tab shows it beside each model, with the percentage at which Nawa compacts it.